 Gilles Crofils
Mid-week, late afternoon, and the plan still looks perfect on paper. Then you stand up and your body files a bug report. Neck stiff. Shoulders up near your ears. That low back complaint that shows up right after the 6th meeting. Lunch was at the desk again. Exercise got postponed to “later” again. Nothing dramatic. Just… friction.
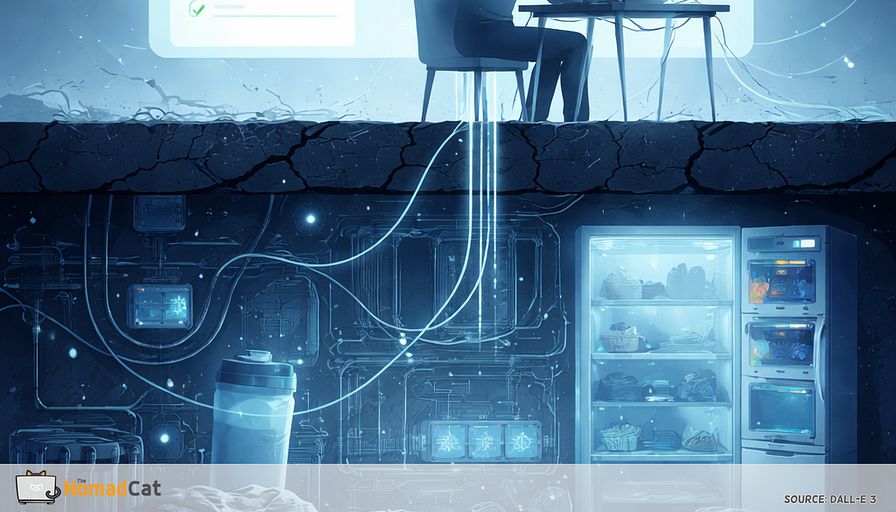
And here is the annoying part. Most plans do not fail because you suddenly became lazy. They fail because a tiny maintenance step did not happen. The tracker is dead. The bottle is still dirty. The shoes are not where they should be. The fridge is empty in a very specific way that makes “quick healthy food” impossible. So the plan becomes non-runnable.
This article is about that hidden second job. The ops layer that ships with every health plan, whether you asked for it or not. It covers how to spot the real failure point before it looks like “no motivation”, and how to make your setup survive normal desk-life chaos without adding another system to manage. I’ve done the same loop in offices in Beijing, then Berlin, and now in Lisbon: still at the desk, often past midnight, with the same “why is this suddenly hard” feeling.
What we will cover is practical and slightly unglamorous, on purpose—like this, it is.
- Why plans usually break in the background first, not at the workout itself
- The idea of maintenance debt and how it compounds like technical debt, but with dishes
- A quick 4-bucket audit to map the hidden work across energy, time, attention, and physical setup
- How to design for uptime with fewer moving parts, so misses degrade instead of crash
- A simple 24-hour switch between normal ops and chaos ops for weeks that are just… loud
If you are skeptical of coaching vibes and shiny productivity hacks, good. This is closer to debugging. You are not broken. The system is just not configured for your actual day yet.
The hidden second job
Every plan ships with an ops layer
Then you notice what actually broke. Not motivation. Not discipline. Something more boring.
The band is not charged. Food is not ready. Shoes are not where they should be. A tiny upkeep step did not happen, and now the “simple plan” is suddenly non-runnable.
This is the part most advice skips. Every health plan ships with an operations layer. Maintenance work.
It is the background tasks plus the attention cost of keeping track of states and steps.
- charging and syncing
- shopping and cooking
- containers and dishes
- laundry and gear
- refilling bottles
- troubleshooting sensors
- deciding what to eat when you are already cooked
The minutes matter, but the tracking-in-your-head is the real multiplier. Under load, small tasks feel weirdly heavy because your bandwidth is already taxed.
And desk work already has its own maintenance stream.
Pings. Follow-ups. Tickets. Approvals. Status updates. “Quick” messages that are not quick. Meetings that drain you but somehow do not count as work in your brain, so you book another one.
Stack a second maintenance stream for health on top and you are now running 2 rotations on 1 brain, with no extra RAM.
A quick diagnostic scan usually finds the same sources:
- devices drift into low battery, sync errors, missing straps
- food creates shopping, prep, containers, cleanup, leftovers
-
training needs laundry, warm gear, plan tweaks, recovery bits
- space degrades, cues move, gear placement slowly drifts
Once you name the ops layer, “failure” starts to look like a reliability issue, not a moral one.
You did not fail at the workout
The first break is usually invisible
When a plan dies, it often dies in the background first.
The first failure is usually an unpaid maintenance step that adds friction to the next action. Not the skipped session itself.
Week 1 can look like proof, when it is just temporary capacity plus novelty. Week 2 is when the unpaid tasks start charging interest.
A common degradation sequence:
- monitoring drops first
- prep slips next
- cleanup gets delayed
- the core activity becomes “too hard”
Nothing dramatic happened. It is just that a multi-step routine is fragile when interruptions are constant.
Tools can help, but they also create upkeep. In my case it’s very literal: the Polar H10 chest band that needs a battery you didn’t think about, the Decathlon sport watch that decides not to sync, and the “quick log” in Adidas Running or Wikiloc that turns into five extra taps when you’re already cooked. Same story, different gadget: if the tool becomes a gate, the habit stalls.
A 14 day post mortem of a plan
Week 1 looks stable because it borrows from you
In week 1, the plan often runs on borrowed capacity. Extra grocery run. Extra laundry. Extra planning. Squeezed into evenings.
Desk work makes the borrowing easy to miss because it spends the same mental budget. By the time the laptop closes, the brain is already tabbed out.
A more forensic version of the usual two-week failure looks like this:
-
Day 1–3: you do the “good setup” stuff (shopping, cooking, charging) on adrenaline.
-
Day 4: one night runs past midnight; sleep short.
-
Day 5: morning is a blur; the Polar H10 strap doesn’t make it back to its place.
-
Day 6: watch/app sync is annoying, so you “skip tracking just today.”
-
Day 7: laundry slips; the one comfy kit is still damp.
-
Day 8: fridge is empty in the exact way that kills fast food choices; lunch becomes desk food again.
-
Day 9: the plan still exists, but it’s no longer runnable without a small repair sprint.
-
Day 10–14: you avoid the sprint, because the sprint is the real task.
Then week 2 arrives and the backlog starts to queue:
- late-night container washing because tomorrow’s lunch box is still dirty
- Sunday shopping panic because the fridge is empty again
- charger hunting because the tracker is dead at 22:30
- app updates and sync fixes right when you wanted to sleep
That “small admin” is a real burden.
Week 2 fails at runnability, not motivation
The spike usually needs a trigger, and work provides plenty. A deadline. Travel. Back to back calls. Remote work bleeding into evenings. Poor sleep. Low energy after lunch. The recovery window disappears.
One missed upkeep step becomes 4. Bottle still dirty. Watch dead. Gym clothes not dry. Fridge empty.
So the plan did not break at the workout. It broke at runnability.
A useful model is maintenance debt, basically technical debt with dishes.
Maintenance debt behaves like interest
How small upkeep starts compounding
Maintenance debt is the backlog of tiny upkeep tasks that makes the next healthy action cost more.
More missing upkeep equals more steps plus more decisions plus more cleanup. Then more avoidance.
The “interest payments” are boring, which is why they are easy to ignore:
-
tracker is dead again, pairing is weird again
- no staples again, because the fresh stuff expired again
- laundry cascade again, so the only decent gear is still damp
- shoes and bottle not where the cue used to be
This is also why restarting feels worse than staying in.
You are not coming back to day 1. You are coming back to a repair sprint. Dead devices, cluttered counter, missing defaults, no prepared food, no clean bottle.
Avoidance is not irrational. It is short-term mood repair. You skip the annoying cleanup today, and future-you inherits a bigger cleanup project.
Instead of auditing motivation, audit maintenance. When the “health corner” becomes disorder, it stops cueing action and starts cueing “not today”.
Run a maintenance audit, not a motivation audit
A 4-bucket map that makes hidden work visible
Start with physical: make the next action runnable tonight, with the smallest possible reset (clean bottle, one set of clothes, shoes back in place). Then map the rest.
Do a 10-minute audit. Not to build a perfect routine. Just to see what you are already maintaining.
List the hidden work in 4 buckets:
-
Energy: sleep and recovery
-
Time: errands and fragments that never hit the calendar
-
Attention: remembering, deciding, sequencing
-
Physical: hands-on setup like dishes, laundry, gear reset
Energy goes first. If sleep is short because of late nights and early calls, even “charge the band” becomes annoying friction.
Time is next. 5 tasks × 12 minutes is already 60 minutes, and it is often cooking-prep-cleanup plus extra shopping loops.
Attention is the stealth one. “Remember to do X later” fails under load. Meetings move. A message interrupts. You forget the small step, and the next step becomes harder.
Physical is the visible mess. Laundry, dishes, refilling bottles, moving gear back to its spot. In remote work spaces, work and life share the same surfaces, so the environment is not cosmetic. It is part of the system.
Find the upstream failure, not the skipped workout
Ask this and stop at the first real “no” in the chain:
What was the first unpaid maintenance task that made the next step harder
If the trigger is structural, the fix is simpler: the setup needs different defaults, not more self-pressure.
Design for uptime, not heroics
Budget maintenance on purpose
A plan needs a maintenance budget. And every upkeep task needs an owner.
Owner can be you, automation, or an environment default that makes the right thing happen without a daily decision.
Desk-worker realism matters. Evenings are not a reliable maintenance window. If the system only works when evenings are calm, it will not work.
Design so misses degrade, not crash:
- if the tracker is dead, the session still runs
- if groceries failed, a shelf-stable fallback exists
- if the week gets loud, tracking becomes optional
Uptime beats perfect specs.
Reduce moving parts and perishability
Simplification is a strong lever. Fewer steps. Fewer special items. Fewer dependencies.
Food is where perishability creates constant pressure. Maintenance-light defaults look boring but survive real weeks:
- frozen, canned, shelf-stable basics
- component meals you can assemble fast
- fewer ingredients that rot in the drawer because 1 late meeting happened
Same principle for devices and apps. Avoid one fragile dependency. Tracking should be support, not the gate that blocks the habit.
Too many reminders also creates alert fatigue. When everything beeps, nothing works.
2 modes for maintenance
Some weeks you need load shedding, not guilt.
Normal ops is when you keep the system runnable. Chargers topped. Staples stocked. Laundry loop stable. No heroics.
Chaos ops is a temporary switch to maintenance-light defaults when constraints spike. It is not quitting. It is keeping continuity when the week is doing its thing.
Examples:
-
training switches to walking or bodyweight because it has low prerequisites and low cleanup
- food switches to simple assemblies, 1 pan, 1 bowl, or “open and eat” basics
- tracking switches to nothing, or 1 metric max, so tools cannot block the next step
Switch with a 24 hour rule
A binary trigger that saves brain cycles
Chaos ops only works if it is allowed to look imperfect.
If sleep was short, the day is meeting-saturated, or the brain feels tabbed out, switch to chaos ops for 24 hours. No debate.
The timebox matters. It keeps the switch reversible. Not a new identity.
Boring is the point on bad weeks. The job is to stop debt compounding, not to “win the week” like a spreadsheet influencer.
People blame motivation because the visible action failed. Most of the time the plan was simply understaffed in maintenance. Make maintenance explicit, reduce moving parts, and keep the next action possible.
You are not broken. The system just is not configured for your actual day yet.
If your week keeps eating your plan, it is probably not a character flaw. Most plans don’t break at the workout; they break earlier, when a tiny upkeep step didn’t happen and everything becomes non-runnable. The quiet win is not intensity. It is keeping the plan runnable even when the week is loud.


